Hiii, there!
I am currently a first-year Ph.D. student at CASIA, Galbot, and EPIC Lab (2026-present). Before that, I received my B.Sc. degree in Computer Science and Technology from Xiamen University (2022-2026). I am currently an intern at Galbot, under the supervision of Prof. He Wang and Prof. Zhizheng Zhang.
I am interested in embodied AI, VLA for manipulation, world models, and video models for robotics.
I am lucky to work closely with Mi Yan, Jiangran Lyu, and Shengliang Deng.

|
|
| *: joint first author; † project lead; ✉ corresponding author(s) |
|
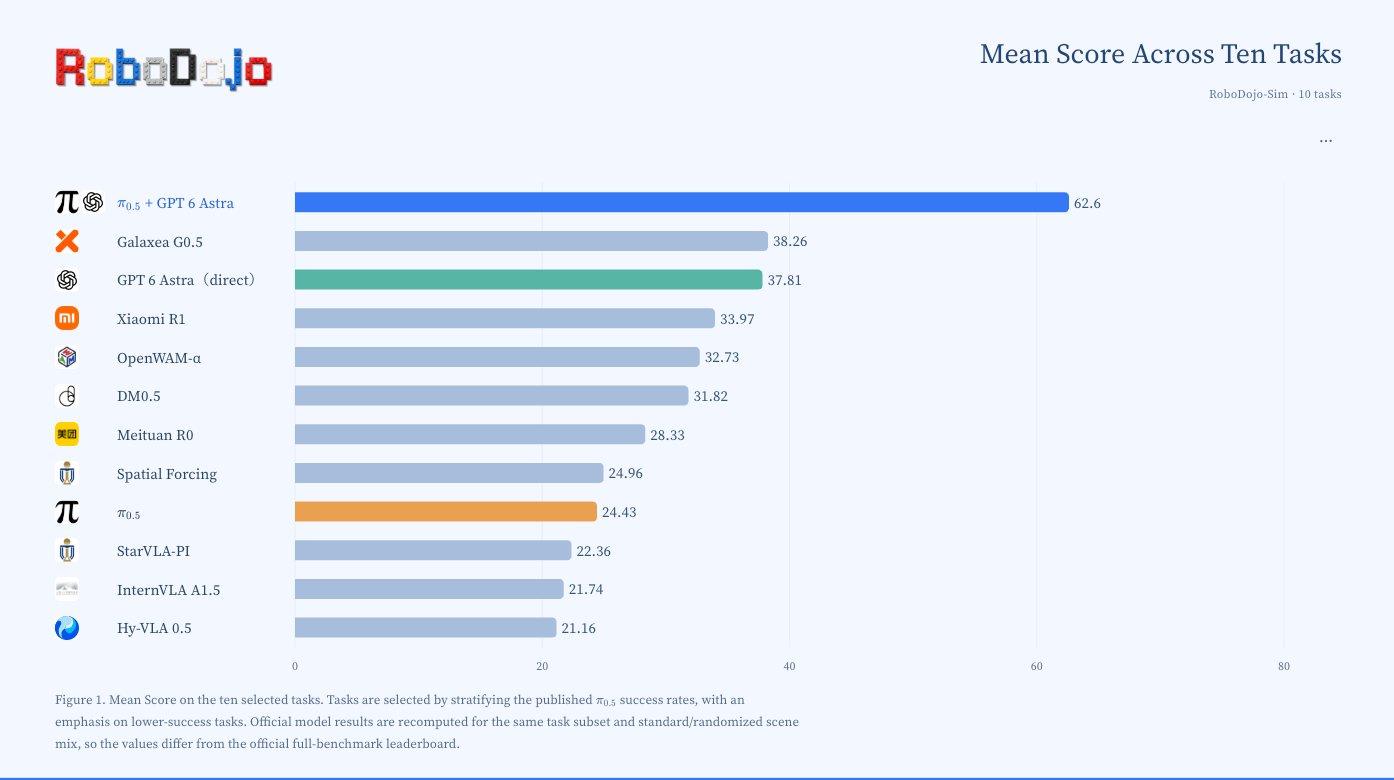
*, Yixin Zheng*, Mi Yan, Li Yi, Zhizheng Zhang✉, He Wang✉ Technical Report, 2026 project page / code / 具身智能之心 / 腾讯科技 / 智能纪元AGI / human five A technical report comparing direct GPT 6 Astra control with a hybrid π0.5 + GPT 6 Astra policy for zero-shot bimanual manipulation. On the selected RoboDojo tasks, the hybrid policy reaches 48% success and a 62.60 mean score, compared with 26% and 37.81 for direct control. |
|
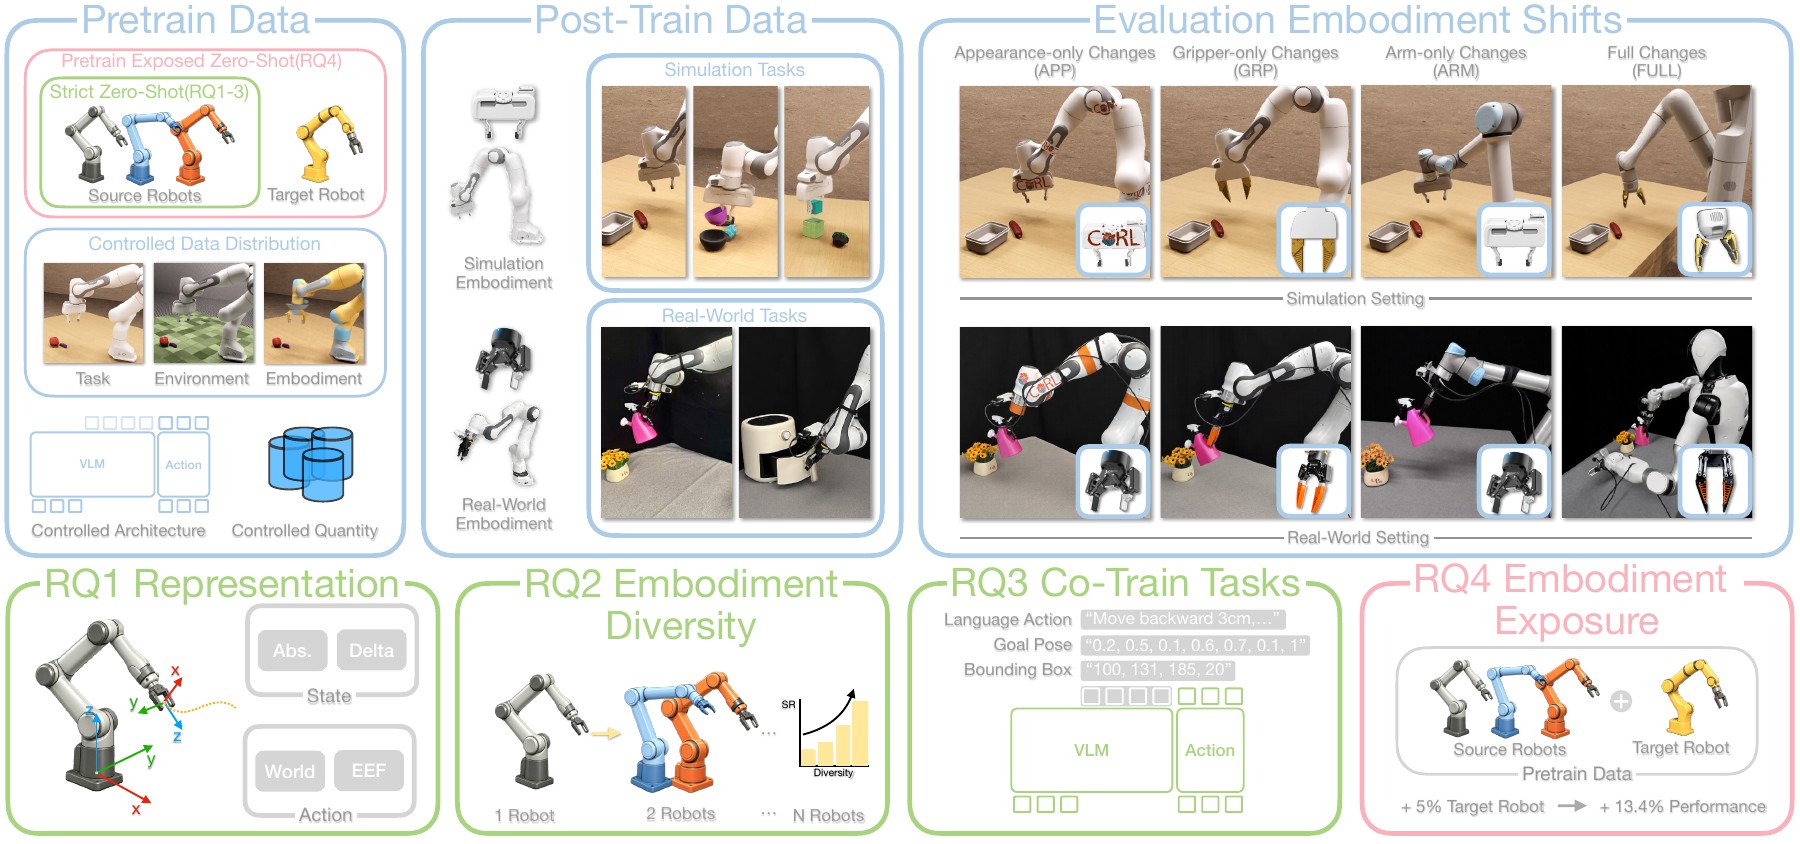
Mi Yan*, Wenhao Zhang*, Zhiqi Zhang*, Yu Peng*, Tangxinyu Wang*, Lingfei Zhai, , Shengliang Deng, Lin Peng, Yaowei Liu, Yuxing Chen, Zhiyuan Wei, Jilong Wang, Jiayi Chen, Jiangran Lyu, Zhizheng Zhang✉, He Wang✉ CoRL, 2026 project page / paper / code ZETA presents a controlled study of zero-shot cross-embodiment transfer for vision-language-action models in tabletop manipulation. |

|
Shengliang Deng*, Mi Yan*, Yixin Zheng*, , Wenhao Zhang, Xiaoguang Zhao, Heming Cui, Zhizheng Zhang✉, He Wang✉ RSS, 2026 arXiv / code / checkpoint StereoVLA is powered by stereo vision and supports zero-shot deployment with high tolerance to camera pose variations. |

|
*, ✉, Youhe Feng*, Zheng Li, Jinhua Song, Yangfan He, Botao Ren, Botian Xu✉ CVPR (top 15%), 2025 arXiv / code ArtFormer introduces a novel transformer-based framework that generates diverse, high-quality 3D articulated objects from text description or single image. |
|
|
|
Ph.D. Student at CASIA (Institute of Automation) 2026.09 - present |

|
Large Embodied Model Researcher 2025.08 - present VLA & Simulation Pipe Engineer |

|
Research Assistant 2025.02 - 2025.05 Research focus: DiT inference optimization |

|
B.Sc. in Computer Science and Technology 2022.09 - 2026 Rank: 1/71; Grade: 97.0 / 100 (3.88 / 4.00) |
|
|
|
Style adapted from Jon Barron. |